Exploring Oversampling Techniques for Imbalanced Datasets
Data drives the world of machine learning and neural networks, yet data quality can make or break a model’s performance.
Imbalanced datasets are those where one class has significantly fewer instances than the other(s), and they are a common occurrence in data science and data mining projects. Some examples include fraud detection and medical diagnosis datasets.
Traditional classification algorithms can perform badly when trained on imbalanced datasets, in the sense that they tend to misclassify the minority class we usually care about most. Oversampling is one of the ways to make more cost-sensitive decisions at the default classification threshold in these situations.
This article will discuss various oversampling techniques, highlighting their advantages and limitations. We will also show how to implement oversampling in Python, and review what the latest evidence says about whether oversampling actually improves the performance of machine learning models.
So, let’s dive in.
In chapter 6 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I review the history of oversampling and SMOTE, the studies that evaluated them with modern classifiers, and test them myself in Python.
A quick note before we start: oversampling does not make a model better at discriminating between classes. What it does is shift the model’s decision boundary so that, at the default classification threshold of 0.5, we make more cost-sensitive decisions, that is, we correctly flag a larger proportion of the minority class.
You can achieve this exact same effect by training on the original, unmodified data and simply adjusting the classification threshold afterward, without oversampling anything at all. We’ll come back to this point throughout the article, and review the evidence in the section Does Oversampling Improve Model Performance?
What is Oversampling?
Oversampling is a data augmentation technique used when dealing with imbalanced datasets where the majority class dominates the minority class. It balances the distribution of classes by increasing the number of samples in the minority class.
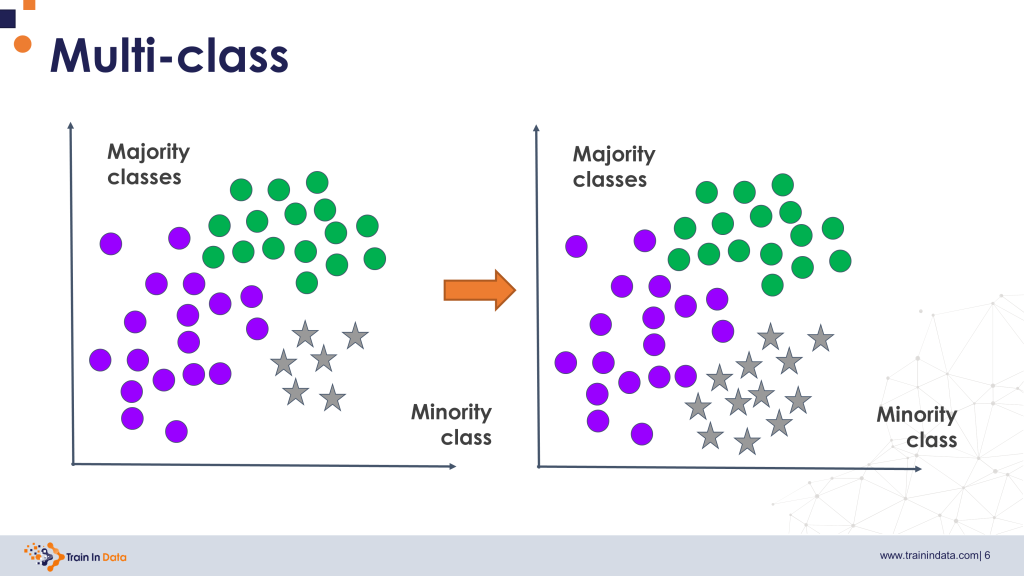
Oversampling increases the number of data points that belong to the minority class by duplicating existing ones or generating new ones by creating synthetic data.
Why Do We Need Oversampling?
In an imbalanced dataset, the majority classes dominate and the minority classes are vastly outnumbered. This imbalance could lead to poor predictions by learning algorithms, particularly for the minority class.
When working with imbalanced datasets, we are usually interested in classifying the minority classes correctly. Hence, the cost of false negatives (i.e., failing to detect the minority class) is much higher than that of false positives (i.e., wrongly identifying a sample as belonging to the minority class).
Traditional machine learning models, like logistic regression and random forests, optimize for balanced metrics, and are naturally geared to working with balanced data. Oversampling shifts the decision boundary toward the minority class by producing a balanced dataset, so at the default threshold, the classifier flags more of the minority class and reduces the cost of false negatives. The same trade-off between false negatives and false positives can be reached by training on the original data and adjusting the classification threshold instead.
How Oversampling Differs from Undersampling
Oversampling and undersampling are resampling techniques for balancing imbalanced datasets, therefore resolving the imbalance problem. They are commonly used to generate suitable training data sets.
While oversampling adds new samples of the minority class, undersampling (or downsampling) reduces the number of samples in the majority class.
When deciding between these two approaches for balancing an imbalanced dataset, one should consider their advantages and limitations.
Undersampling can be effective when the majority class has many redundant or similar samples or when dealing with huge datasets. But it can also lead to a loss of information, resulting in biased models.
On the other hand, oversampling can be effective when the datasets are small and there are limited available samples of the minority class. But, it can also lead to overfitting due to data duplication or the creation of synthetic data that are not representative of the real data.
Keep in mind that this is the traditional view. More recent studies show that neither oversampling nor undersampling makes modern classifiers better at separating the classes, as we’ll see later in this article.
In the rest of the article, we’ll discuss various oversampling techniques.
Why We Show the Oversampling Code
You will still come across random oversampling and SMOTE in plenty of legacy code, older tutorials and Kaggle notebooks. To understand and maintain that code, you need to know what each technique does.
Oversampling may also be useful in a few narrow situations, which we discuss at the end of the article. So, treat the following demos as a reference to understand how each technique works, rather than as a recommendation to oversample your data.
Random Oversampling
Random oversampling selects existing original samples from the minority class randomly and duplicates them to balance out the dataset. In other words, random oversampling duplicates data points from the minority class at random.
This method can be helpful when dealing with small datasets, as it helps increase the number of samples without the need to gather more data.
Let’s see how we can implement random oversampling. We will use the RandomOverSampler from the open-source package imbalanced-learn. So let’s make the necessary imports:
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns

from sklearn.datasets import make_blobs
from imblearn.over_sampling import RandomOverSampler
Now we create a toy dataset with 2 classes, where 80% of the observations belong to the majority class and 20% to the minority class. We use the make_blobs function from Scikit-learn:
X, y = make_blobs(
    n_samples=1600,
    centers=[(0, 0), (5, 5)],
    n_features=2,
    cluster_std=1.5,
    random_state=0)

X = pd.DataFrame(X, columns=['VarA', 'VarB'])
y = pd.Series(y)

X = pd.concat([
    X[y == 0],
    X[y == 1].sample(200, random_state=42)
], axis=0)

y = y.loc[X.index]
After that, we can go ahead and plot our toy dataset:
sns.scatterplot(
    data=X, x="VarA", y="VarB", hue=y, alpha=0.5
)
plt.title('Toy dataset')
plt.show()
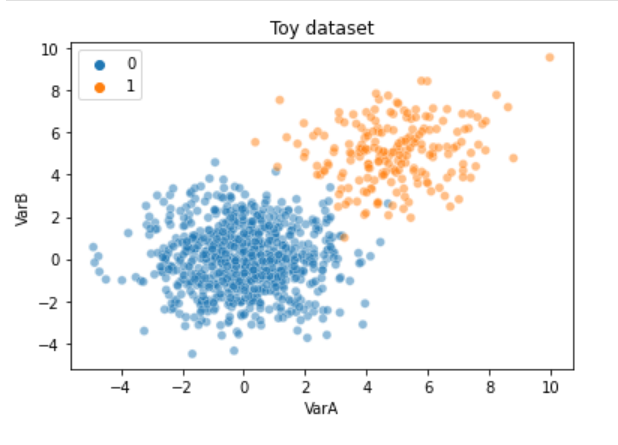
The blue dots in the toy dataset represents the majority class, whereas the orange dots represent the minority class:
We’ll use the following code to select instances from the minority class in a random manner with replacement until the number of observations in the minority class equals the number of observations in the majority class:
ros = RandomOverSampler(
    sampling_strategy='auto',
    random_state=0,
)

X_res, y_res = ros.fit_resample(X, y)
When we apply fit_resample(), the RandomOverSampler() duplicates at random data points from the minority class.
To better understand the result, let’s display the shape of the original data:
X.shape, y.shape
The below output tells us that 1000 samples and two features are in the original data, and 1000 data points belong to the target:
((1000, 2), (1000,))
Now, let’s evaluate the size of the over-sampled dataset:
X_res.shape, y_res.shape
The following output shows the size of the oversampled data. We see that it has 600 samples more than the original data:
((1600, 2), (1600,))
Let’s determine the number of minority class observations before and after oversampling:
y.value_counts(), y_res.value_counts()
The output shows the count of minority and majority class observations before and after oversampling. In the original data, there are 800 instances of the majority class and 200 of the minority. In the oversampled data, there are 800 data points of each class:
(0    800
1    200
Name: count, dtype: int64, 0    800
1    800
Name: count, dtype: int64)
We can wrap up the demo by creating a a scatterplot of the oversampled dataset:
sns.scatterplot(
    data=X_res, x="VarA", y="VarB", hue=y_res, alpha=0.5
)

plt.title('Over-sampled dataset')
plt.show()
Below is our oversampled data set.
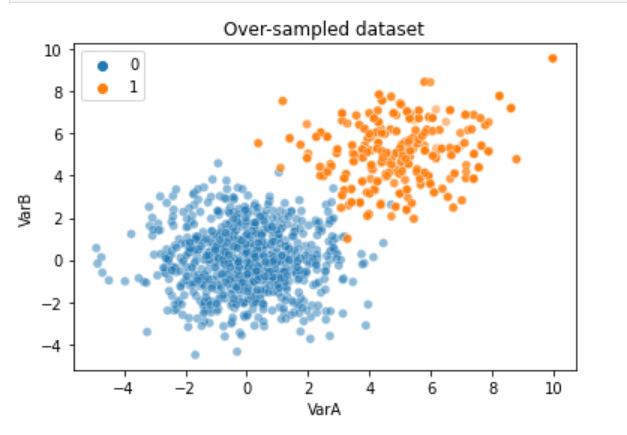
Although there are more instances of the minority class after random oversampling, they may not appear more prominent when displayed because of the overlapping. However, you can see darker orange tones now for the minority class, which correspond to the duplicated instances.
We can now use the resampled dataset, X_res to train our machine learning classifiers. It is important to remember that while we train the models on the balanced dataset, we should test their performance on a test set with the original class distribution.
Advantages of Random Oversampling
The main advantage of random oversampling is its simplicity and ease of implementation. It does not require any complex algorithms or assumptions about the underlying distribution of the data.
It can be applied to any dataset with a class imbalance, including datasets with categorical variables, and does not require prior knowledge about the dataset. And when oversampling is justified, random oversampling tends to work as well as SMOTE, as we’ll see later.
Limitations of Random Oversampling
Random oversampling may lead to overfitting, where the model becomes too specific to the training data and may not generalize well to new data.
The reason is that random oversampling does not add new information to the dataset. The new samples are generated by duplicating existing data. Hence, they do not provide further details about the minority class or classes, and instead, it might just increase their noise.
Random oversampling also distorts the calibration of the model. The model learns a class distribution that does not exist in reality, so it returns inflated probabilities for the minority class.
Random Oversampling with Noise
Random oversampling with noise is a variation of random oversampling, where noise is added to the new samples generated during the oversampling process. The noise is introduced to prevent the exact replication of the minority class instances, which can lead to overfitting.
In this technique, instead of selecting exact replicas of the minority class instances, new data points are generated by introducing random noise into the existing minority class instances. A hyperparameter controls the amount of noise added and can be adjusted to obtain the desired noise level.
Adding noise can help diversify the minority class instances and reduce overfitting, preventing the model from relying too heavily on the exactly replicated minority class instances. You can quickly implement it with imbalanced-learn, by setting the shrinkage parameter of the RandomOverSampler(), which controls the amount of noise added to the new samples.
For a Jupyter notebook with the full implementation, visit our GitHub repository.
SMOTE (Synthetic Minority Oversampling Technique)
SMOTE, which stands for Synthetic Minority Oversampling Technique, is a popular oversampling method used to address class imbalance in machine learning.
The main idea behind the SMOTE algorithm is to generate synthetic data points of the minority class by interpolating between the minority class instances. In other words, SMOTE creates new data artificially.
To achieve this, SMOTE randomly selects a minority class instance and then finds its k nearest minority class neighbors, 5 by default. It then picks one of those neighbors at random, and places a new synthetic instance at a random point along the line that connects the original instance and the selected neighbor.
SMOTE repeats this process until the desired balance between the classes is reached. Note that SMOTE ignores the majority class when it searches for neighbors, and that it relies on interpolation, so it is designed for continuous variables.
You can find a step-by-step explanation of the algorithm in our article on SMOTE in Python.
Let’s see how we can implement SMOTE with imbalanced learn. First, we make the necessary imports:
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns

from sklearn.datasets import make_blobs
from imblearn.over_sampling import SMOTE
Now, let’s create a toy dataset with 2 classes, 80% of them belonging to a majority class:
X, y = make_blobs(
    n_samples=1600,
    centers=[(0, 0), (5, 5)],
    n_features=2,
    cluster_std=1.5,
    random_state=0)

X = pd.DataFrame(X, columns=['VarA', 'VarB'])
y = pd.Series(y)

X = pd.concat([
    X[y == 0],
    X[y == 1].sample(200, random_state=42)
], axis=0)

y = y.loc[X.index]
Now, lets implement SMOTE. We need to define specific parameters to over sample only the minority class, and define the number of k-nearest neighbors for the interpolation:
sm = SMOTE(
    sampling_strategy='auto',
    random_state=0,
    k_neighbors=5,
)

X_res, y_res = sm.fit_resample(X, y)
With fit_resample() we’ve created the synthetic data.
Let’s now compare the original and new data sizes. Let’s display the size of the original data:
X.shape, y.shape
Here’s the output indicating 1000 observations and two features in the X dataset and 1000 corresponding labels in the y dataset.
((1000, 2), (1000,))
To find the size of oversampled data, we use the following code.
X_res.shape, y_res.shape
It leads us to the following output, where we see that the final training data contains 1600 observations:
((1600, 2), (1600,))
We want to identify the number of minority class observations before and after applying SMOTE.
y.value_counts(), y_res.value_counts()
The below output tells us that in the original dataset, there are 800 observations of class 0 and 200 observations of class 1. After applying SMOTE, the resampled dataset now has 800 observations of each class:
(0    800
1    200
Name: count, dtype: int64, 0    800
1    800
Name: count, dtype: int64)
We can now use the following code to generate a scatter-plot for our oversampled dataset.
sns.scatterplot(
    data=X_res, x="VarA", y="VarB", hue=y_res, alpha=0.5
)

plt.title('Over-sampled dataset')
plt.show()
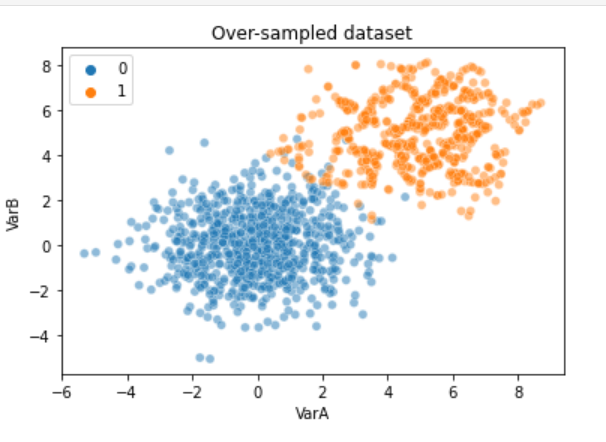
So you can notice that there are now new observations in between the original data points of the minority class.
Advantages of SMOTE
SMOTE can generate new samples based on existing ones, which helps shift the decision boundary toward the minority class without simply duplicating data points, unlike random oversampling.
Limitations of SMOTE
One of the main drawbacks of SMOTE is that it may introduce noise with the synthetic instances, especially when the number of nearest neighbors is set too high. Additionally, SMOTE may not work well on tightly clustered minority class instances or when there are few instances in the minority class.
SMOTE also assumes that points lying between nearby minority class examples are plausible members of that class. That is not always the case, and if we can’t trust the synthetic data points, we can’t fully trust a model trained on them.
Finally, recent studies show that SMOTE does not improve the performance of strong classifiers, and that it does not offer a clear advantage over the simpler random oversampling. We discuss this evidence in detail below.
In chapter 6 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I explain why SMOTE looked so promising for two decades, and why its apparent advantage vanishes with strong classifiers and tuned thresholds.
SMOTE Variants
Several SMOTE variants are available to address these limitations. In fact, by 2018, researchers had already developed at least 90 SMOTE-based oversampling methods (Fernández et al., 2018). Here, we discuss the most popular ones.
Borderline-SMOTE
One of the key limitations of SMOTE is that it generates synthetic samples along the line connecting the minority class sample to its nearest neighbors. This approach can lead to the misclassification of synthetic samples as the majority class, especially when the minority class sample is close to the decision boundary.
Borderline-SMOTE addresses this issue by only generating synthetic samples for minority-class samples close to the decision boundary. Under the hood, Borderline SMOTE uses templates to create the synthetic data observations from the minority, for which the majority of the neighbors are from the opposite class. Then, it interpolates between these instances and their minority class neighbors.
SVM-SMOTE
SVM-SMOTE is an alternative to Borderline SMOTE, where the data points that are used to create the synthetic data are the support vectors of a support vector machine separating the classes.
The synthetic data is created by interpolating between each minority class support vector and its nearest neighbors of the minority class. Hence, it creates more data points at the decision boundary.
Other SMOTE variants
In addition to the SMOTE variants mentioned above, there are more SMOTE alternatives like K-means SMOTE and variations that are also suitable for discrete and categorical variables, like SMOTE-N and SMOTE-NC. Like SMOTE, these variants were mostly evaluated with weak classifiers, and there is little evidence that they improve the performance of modern ones.
Adaptive Synthetic Sampling (ADASYN)
ADASYN is an alternative oversampling technique that aims to address the issue of generating synthetic samples in regions of the feature space that are closer to the decision boundary. It works by developing more synthetic samples for minority class samples that are more difficult to learn, i.e., those closer to the decision boundary.
ADASYN uses as templates for the synthetic data samples from the minority class if some of their closest neighbours are from opposite classes. The more neighbours from the opposite class, the more likely it is to be used as template. After selecting the templates, it then generates the examples by interpolation between the template and the closest neighbors from its same class.
You can find a detailed explanation and a Python implementation in our article on ADASYN.
Does Oversampling Improve Model Performance?
For more than a decade, SMOTE was recommended almost automatically for imbalanced data. So, does oversampling actually make machine learning models better?
Why SMOTE Looked So Promising
SMOTE was introduced in 2002, when random forests were new and modern gradient boosting libraries like XGBoost, LightGBM and CatBoost did not exist. Its original evaluation focused on decision trees and Naive Bayes, for which it showed some performance gains.
The studies that followed kept this setup. A review of 72 oversampling methods found that most were evaluated with decision trees, support vector machines, k-nearest neighbors and other relatively simple classifiers (Hassanat et al., 2022).
Most of these studies also measured performance with threshold dependent metrics, like recall, F1-score or the geometric mean, and rarely reported the classification threshold. That gave SMOTE an easy advantage: by moving the decision boundary toward the minority class, it increases these metrics at the default threshold of 0.5.
To SMOTE, or Not to SMOTE?
In 2022, Elor and Averbuch-Elor revisited oversampling in their article “To SMOTE, or not to SMOTE?”. They compared random oversampling and several SMOTE variants with weak and strong classifiers across 73 datasets, tuning the hyperparameters and repeating each experiment across different data splits.
When predictions were classified at the default threshold of 0.5, every classifier seemed to benefit from oversampling, including XGBoost and CatBoost. But once the decision threshold was optimized, models trained on the original data matched or beat the oversampled ones for AdaBoost, LightGBM, XGBoost and CatBoost.
The ROC-AUC told the same story: oversampling did not improve the ranking performance of the strong classifiers. Only weaker models, like the multilayer perceptron and support vector machines, showed a clear benefit. And SMOTE did not offer a clear advantage over random oversampling, even at the default threshold.
What Other Studies Say About Oversampling
One study is not enough to dismiss a method used for more than two decades, so in my book I reviewed the studies that evaluated random oversampling or SMOTE with random forests and gradient boosting machines, using threshold independent metrics like the ROC-AUC or the PR-AUC. The number of studies that meet these criteria is surprisingly small.
The following table summarizes them:
| Study | Models | Datasets | Conclusion |
|---|---|---|---|
| Hasanin et al. (2019) | Random forest, gradient boosting | 2 large datasets | Random oversampling and SMOTE did not beat the original data |
| Kim & Hwang (2022) | AdaBoost, XGBoost, random forest | 31 datasets | No improvement in PR-AUC or ROC-AUC |
| Kim et al. (2024) | Random forest, XGBoost | 1 clinical dataset | No clear improvement |
| Gurcan et al. (2024) | Random forest, XGBoost | 5 cancer datasets | Random oversampling helped in 1 of 5 datasets, without error estimates |
| Isangediok & Gajamannage (2022) | Random forest, XGBoost | 2 datasets | No consistent gain with SMOTE |
The pattern is clear: the more rigorously a study accounts for variability, the less evidence it finds that SMOTE or random oversampling improves random forests, gradient boosting machines or AdaBoost.
Oversampling Shifts the Decision Threshold
Oversampling does not make a model better at ranking observations. What it does is shift the predicted probabilities, so that more observations are classified as the minority class at the default threshold of 0.5.
We can obtain the same decisions by training the model on the original data and lowering the threshold, without duplicating observations or generating synthetic data. And on top of that, the model trained on the original data returns better calibrated probabilities.
In fact, the theory backs this up. Resampling the training data and using cost-sensitive learning with class weights are equivalent to shifting the classification threshold.
In chapter 6 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I discuss each of these studies in detail, and show in Python that the apparent gains of random oversampling and SMOTE with XGBoost vanish once the threshold is tuned.
When Could Oversampling Still Be Useful?
According to Elor and Averbuch-Elor, oversampling may help when you are restricted to a weak classifier, although a strong classifier trained without oversampling still tends to perform better. It may also help when you can’t adjust the decision threshold, for example, because of legacy software or models that don’t return probabilities.
Even then, random oversampling is as effective as the more complex SMOTE variants. So, start simple.
For most projects, the modern approach is to train a strong classifier, like xgboost, lightGBM or catboost, on the original data, evaluate it with a threshold independent metric, and tune the threshold to make the decisions your application needs. I walk you through this approach in my guide to machine learning with imbalanced data.
Wrap-up
Oversampling techniques, such as random oversampling, SMOTE, and their variants, increase the number of minority class observations, either by duplicating existing ones or by creating synthetic data. They are easy to implement in Python with imbalanced-learn.
For two decades, these methods were considered an effective way to deal with imbalanced datasets. However, recent studies show that they do not improve the performance of strong classifiers, and that their apparent gains come from evaluating models at the default threshold of 0.5.
So, before you oversample, train a strong classifier on the original data and tune the threshold. If you want to know more about the alternatives, read our articles on undersampling and on whether you should use imbalanced-learn in 2026.
Need help figuring out where to start? Our book Imbalanced Data: Myths, Mistakes and Modern Solutions walks you through what works, and what doesn’t, when working with imbalanced data.
References
- Chawla, N. V. et al. 2002. SMOTE: Synthetic Minority Over-sampling Technique. Journal of Artificial Intelligence Research.
- Elor, Y. and Averbuch-Elor, H. 2022. To SMOTE, or not to SMOTE?. arXiv.
- Fernández, A. et al. 2018. SMOTE for Learning from Imbalanced Data: Progress and Challenges, Marking the 15-year Anniversary. Journal of Artificial Intelligence Research.
- Galli, S. 2026. Imbalanced Data: Myths, Mistakes and Modern Solutions.
- Hassanat, A. et al. 2022. Stop Oversampling for Class Imbalance Learning: A Critical Review. IEEE Access.
