Does Undersampling Help with Imbalanced Data?
Undersampling is one of the most popular techniques to tackle imbalanced data. The idea is simple: if one class has many more observations than the other, we remove observations from the larger class until the class distribution is more balanced.
Random undersampling, NearMiss, Tomek links, edited nearest neighbors and many other undersampling methods have been around for decades. They are available in the Python library imbalanced-learn, and they appear in almost every tutorial on imbalanced classification.
But does undersampling actually help? Does a model trained on undersampled data perform better than the same model trained on the original data? In this article, I’ll review the evidence, and show you how to apply each undersampling technique in Python.
In chapter 5 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I review the scientific literature behind each undersampling method, and test them with modern classifiers across 37 datasets. This article summarizes what I found.
The short answer, up front: undersampling does not make a model better at discriminating between classes. What it does is shift the decision boundary so that, at the default classification threshold of 0.5, the model flags a larger proportion of the minority class.
You can get that exact same effect by training on the original data and lowering the classification threshold, without discarding a single observation. The rest of this article walks through the evidence for that claim.
In this article, we will cover:
- What undersampling is, and how it compares to oversampling
- The advantages and disadvantages of undersampling
- What the literature and my experiments say about whether undersampling works
- When to use undersampling, and what to do instead
- How to apply random undersampling, NearMiss, condensed nearest neighbors, Tomek links, edited nearest neighbors, instance hardness threshold, one-sided selection, the neighborhood cleaning rule and cluster centroids in Python with imblearn
- How to check whether undersampling improves your model, and the mistakes to avoid
What Is Undersampling?
Undersampling is a resampling technique that reduces the number of observations in the majority class of an imbalanced dataset. It removes samples from the majority class until it matches the size of the minority class, or until a certain criterion is met.
In an imbalanced dataset, one class has many more observations than the other. In fraud detection, for example, legitimate transactions (the majority class) may outnumber fraudulent ones (the minority class) by 100 to 1, or more.
When the class distribution is skewed like this, machine learning models are said to favor the majority class, and miss many observations of the minority class. Undersampling aims to fix this by giving the model a more balanced dataset to learn from.
Undersampling for Imbalanced Classification
Undersampling is applied only to the training dataset. We leave the test set untouched, because we want to know how the model performs on the real class distribution.
The amount of undersampling is controlled by the sampling strategy, that is, the desired ratio between the minority and the majority class after resampling. The most common target is a 1:1 ratio, where both classes end up with the same number of observations, but any ratio can be specified.
Types of Undersampling Techniques
Undersampling techniques differ in how they choose which examples of the majority class to remove. We can group them into five families:
- Random undersampling removes examples from the majority class at random.
- Methods that select examples to keep, like NearMiss and condensed nearest neighbors (CNN), keep the majority class examples that are most informative, according to some criteria, and discard the rest.
- Methods that select examples to delete, like Tomek links, edited nearest neighbors (ENN) and the instance hardness threshold, remove majority class examples that are noisy, ambiguous or hard to classify.
- Methods that combine keep and delete, like one-sided selection (OSS) and the neighborhood cleaning rule (NCR), apply both ideas in sequence.
- Cluster centroids replaces the majority class with the centroids of clusters found with k-means.
Methods that select examples to keep and random undersampling are also called fixed undersampling methods, because they reduce the majority class to a size defined by the user. Methods that delete examples are also called cleaning methods, because they “clean” the decision boundary, and the number of observations they remove depends on the data.
Most of these undersampling methods rely on k-nearest neighbors (KNN) to find the examples to keep or remove. We’ll go through each of them in detail, with Python code, later in this article.
Undersampling vs Oversampling
Undersampling and oversampling are the two main types of resampling. Undersampling removes examples from the majority class, while oversampling adds examples to the minority class.
Oversampling can duplicate existing examples of the minority class, as random oversampling does, or create synthetic examples, as SMOTE and ADASYN do. Both produce a larger, balanced dataset, whereas undersampling produces a smaller one.
When to Choose Undersampling or Oversampling
The traditional advice says to use undersampling when we have lots of data, and the majority class is so well represented that removing some of its examples causes no loss of information. When data is scarce, we can’t afford to throw observations away, so oversampling would be the better choice.
Oversampling comes with its own risk: duplicating or interpolating examples of the minority class can lead to overfitting. As we’ll see shortly, neither undersampling nor oversampling makes modern classifiers better at separating the classes, so the choice matters less than it seems.
Hybrid Sampling
Hybrid sampling combines oversampling and undersampling. SMOTETomek, for example, creates synthetic examples with SMOTE and then removes Tomek links, while SMOTEENN removes noisy examples with ENN after SMOTE.
Advantages and Disadvantages of Undersampling
Advantages of Undersampling
- Faster training: a smaller training set reduces training time and storage needs, which can matter for huge datasets.
- Balanced dataset: it produces a balanced class distribution, so the model predicts the minority class more often at the default threshold.
- Simplicity: random undersampling is easy to understand and to implement, even without specialized libraries.
Disadvantages of Undersampling
- Information loss: we discard data that may contain useful patterns, and that may have been expensive to collect.
- Biased sample: the remaining majority class examples may not be representative of the original population.
- Miscalibrated probabilities: the model learns a class distribution that does not exist in reality, so its predicted probabilities are inflated for the minority class.
- Slow cleaning methods: methods based on KNN are computationally expensive and don’t scale to big datasets.
- No performance gain: as we’ll see next, undersampling does not improve the performance of modern classifiers.
Does Undersampling Help? What the Literature Says
Undersampling Was Developed for Weak Classifiers
Most undersampling methods were developed between the late 1960s and the early 2000s, when k-nearest neighbors and decision trees were the go-to classifiers. The original studies evaluated them with those weak learners, and with threshold dependent metrics like accuracy, error rate, recall or the geometric mean.
The classification threshold was rarely reported, so we can assume that these metrics were calculated at the default threshold of 0.5. And even then, the improvements were not consistent across datasets and classifiers.
In other words, undersampling methods have only looked successful when models were evaluated with threshold dependent metrics and the threshold was not adjusted. That is exactly the same flaw behind the hype around SMOTE, as I discuss in my article Should You Use Imbalanced-Learn in 2026?.
Undersampling with Strong Classifiers
What about modern classifiers like random forests and gradient boosting machines? Only a handful of studies evaluated undersampling with strong classifiers and threshold independent metrics, like the ROC-AUC or the PR-AUC, and most of them found that undersampling gave little or no improvement.
For example, Wainer (2023) found no statistically significant difference in ROC-AUC between models trained with or without undersampling across 58 datasets. Kim et al. (2022) found that undersampling decreased, rather than increased, the performance of the models across 31 datasets.
The only convincing improvement I found in the literature comes from Hasanin et al. (2019), on a dataset with 1.5 million observations and only 0.27% positive cases. So undersampling might help in very specific scenarios, like huge datasets with extreme imbalance, where discarding observations still leaves plenty of data to train the model.
Does Undersampling Help? My Experiments
Undersampling Across 37 Imbalanced Datasets
Given the scarce evidence, I ran the experiments myself. I combined random undersampling, the instance hardness threshold and the cleaning methods (ENN, RENN, AllKNN, Tomek links, CNN, NCR and OSS) with random forests, AdaBoost, scikit-learn’s gradient boosting machine, CatBoost, XGBoost and LightGBM, and evaluated them across 37 imbalanced datasets.
The code and results are available in my resampling experiments repository. Each model was evaluated with cross-validation, and I report the mean and standard deviation of each metric, together with statistical tests to determine whether the differences were significant.
Random Undersampling Does Not Improve the ROC-AUC
The following figure shows the ROC-AUC (left) and the Brier score (right) of the models trained on the original data (blue) and after random undersampling (green) for 5 of the 37 datasets. The red band shows the performance of a random forest trained on the original data, and the horizontal brackets mark statistically significant differences.
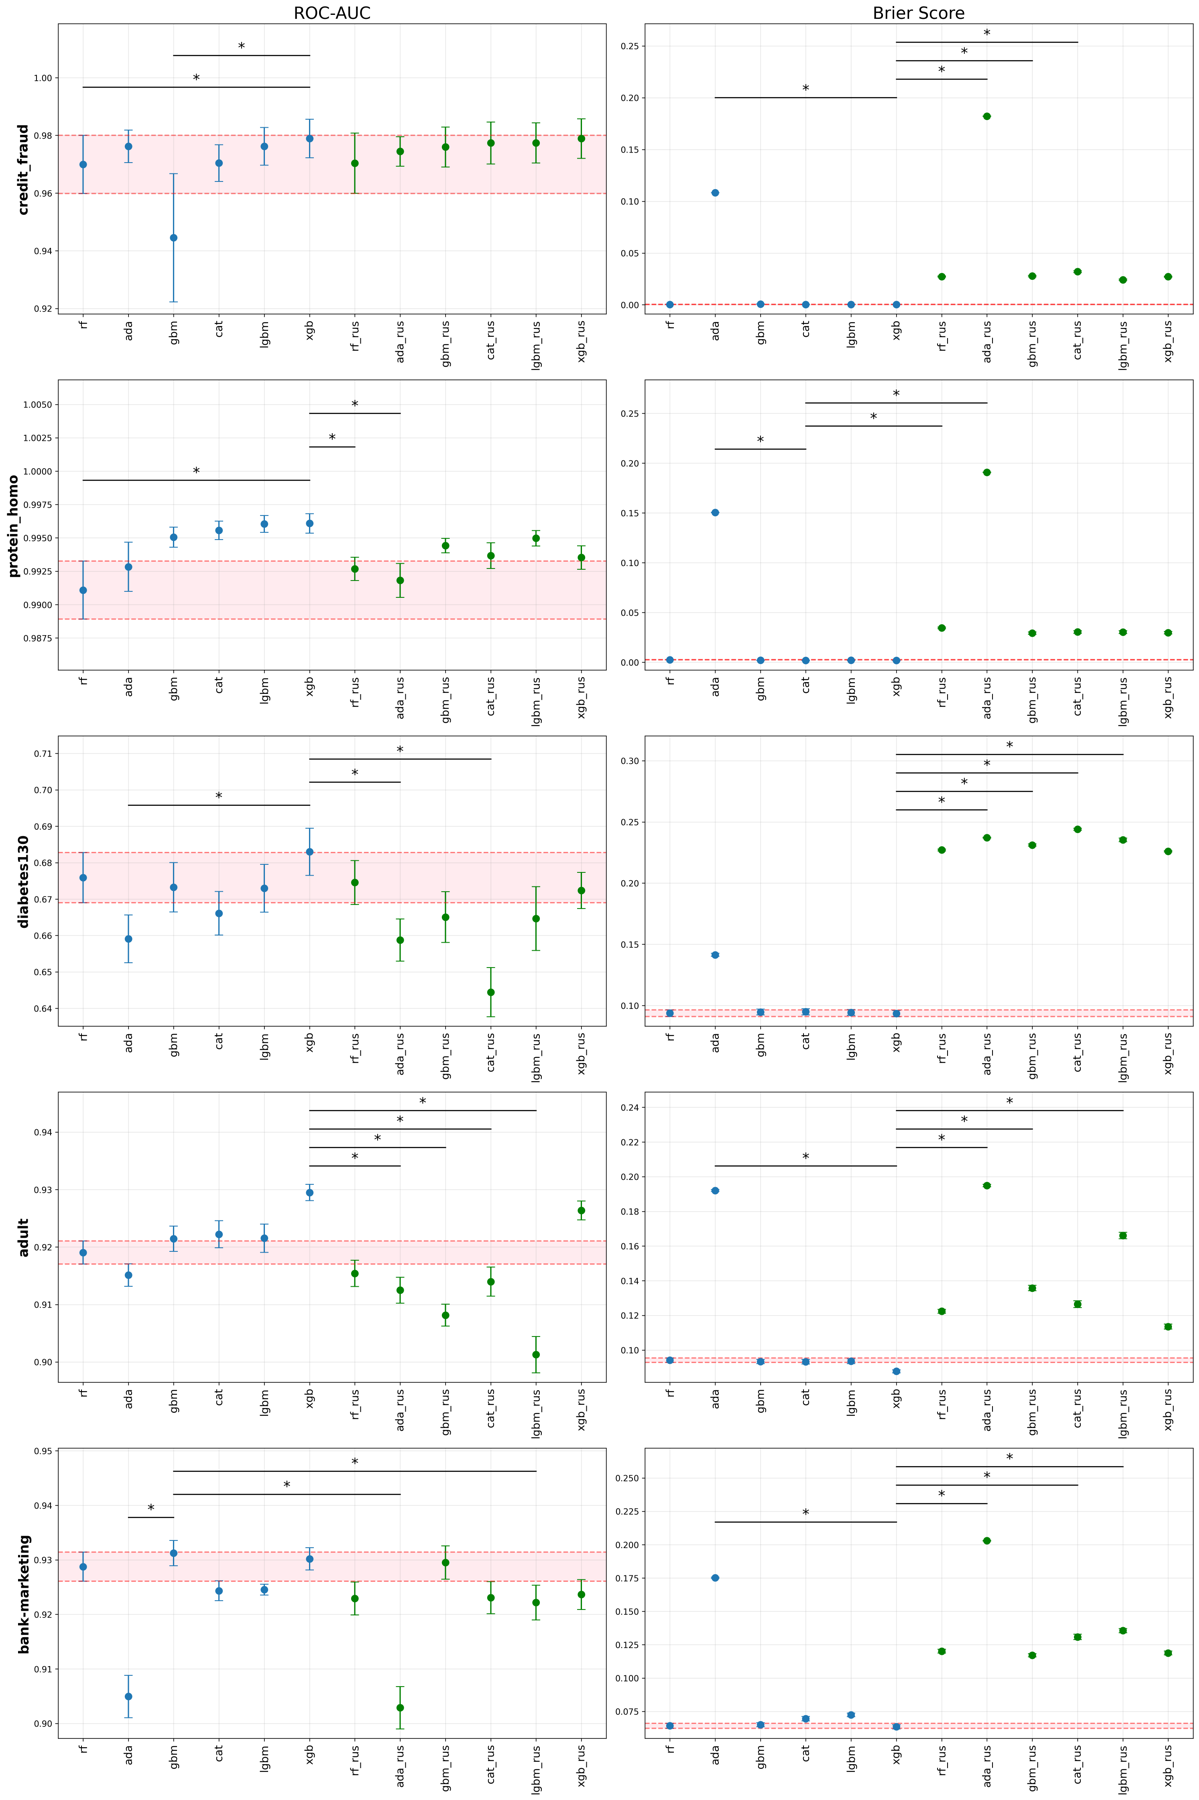
In no case did a model trained after random undersampling outperform the same model trained on the original data. The results were consistent for the remaining 32 datasets.
On top of that, undersampling consistently increased the Brier score. Since the ROC-AUC barely changed, this means that undersampling made the predicted probabilities less accurate, in other words, it miscalibrated the model.
Undersampling Shifts the Decision Threshold
What about threshold dependent metrics? The following figure shows the balanced accuracy of each model (left), and the threshold that maximized the balanced accuracy (right).
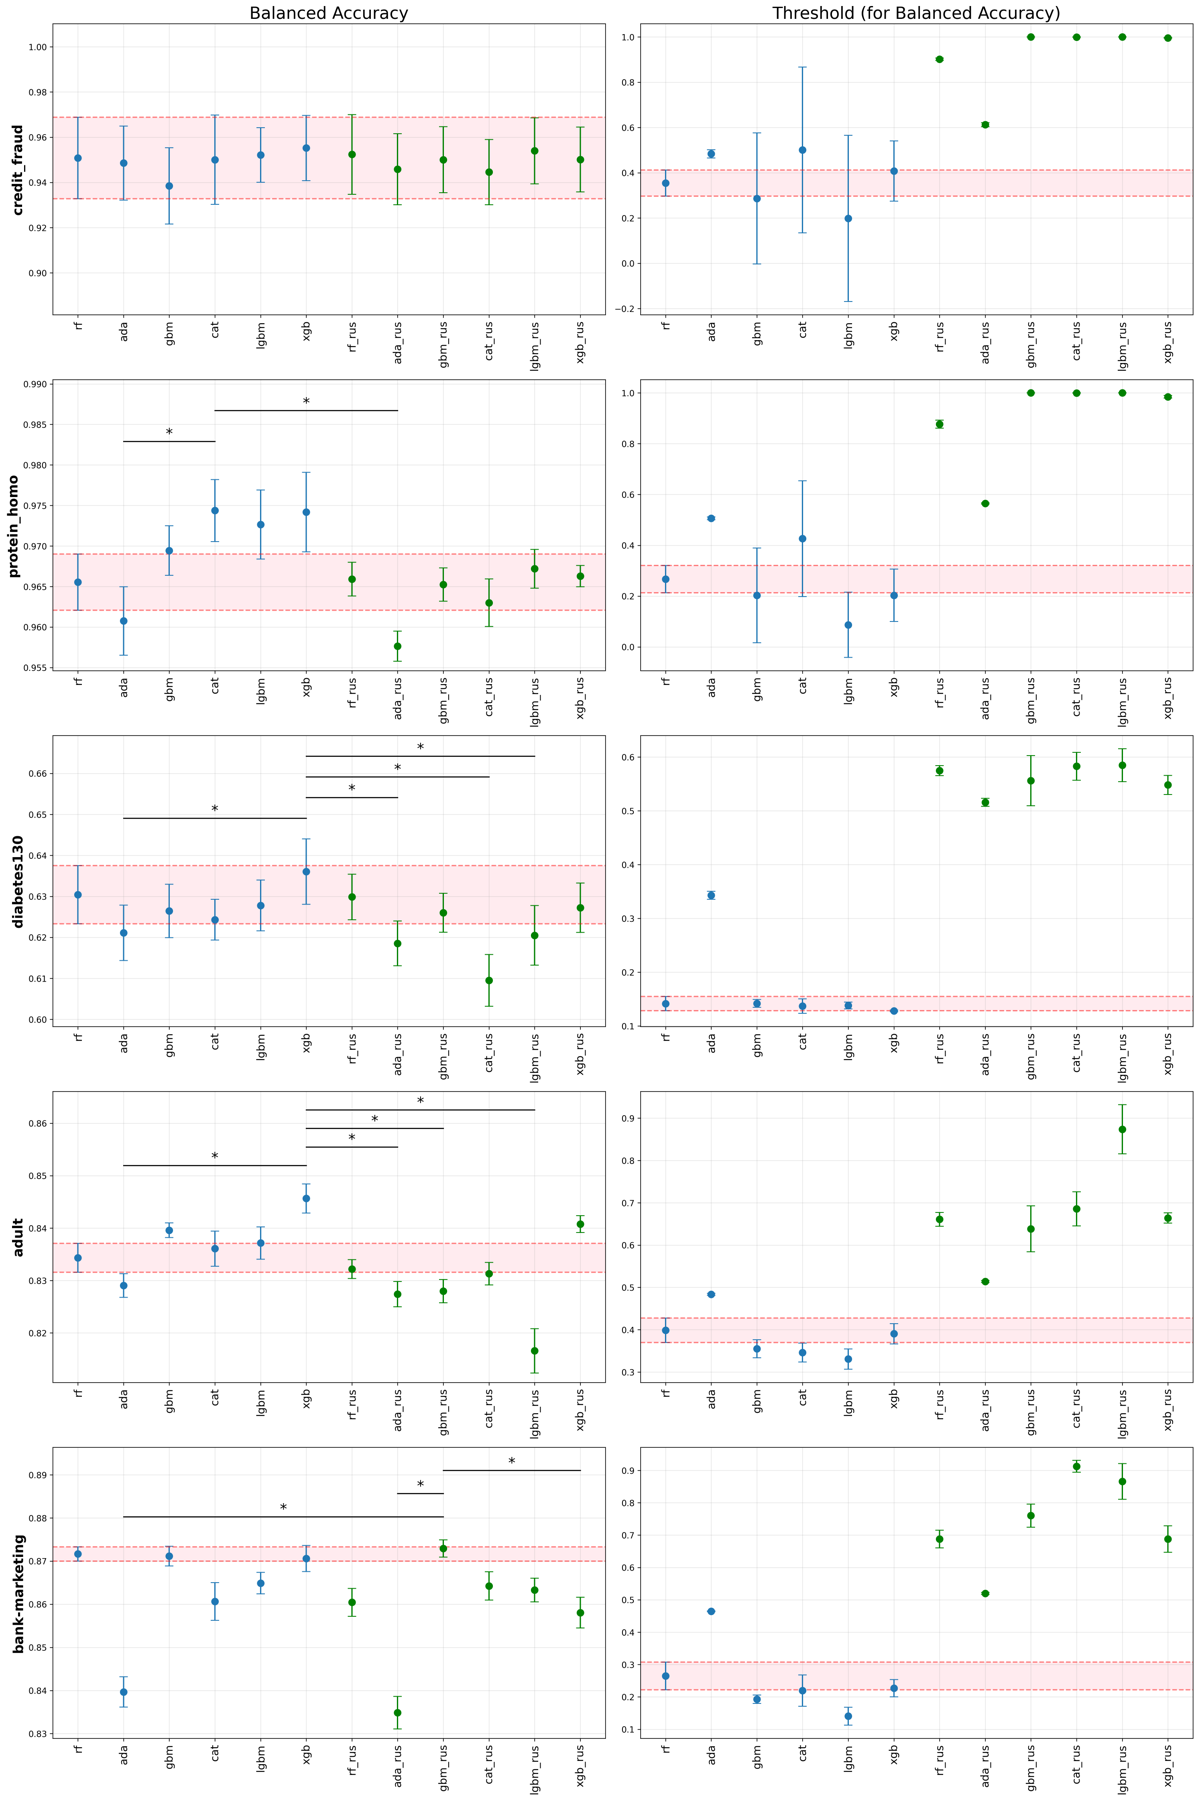
When the balanced accuracy was calculated at its optimal threshold, random undersampling did not improve it. Notice how the models trained on the original data reach their best balanced accuracy at thresholds below 0.5, while models trained after undersampling reach it at higher thresholds.
This is the key point: undersampling changes the threshold at which we should classify an observation as the minority class. The model’s ability to rank observations, from most to least likely to belong to the minority class, stays the same.
Cleaning Undersampling Methods
Cleaning methods remove a number of observations that depends on the data. The following figure shows the percentage of the training set removed by each cleaning method in 5 of the datasets.
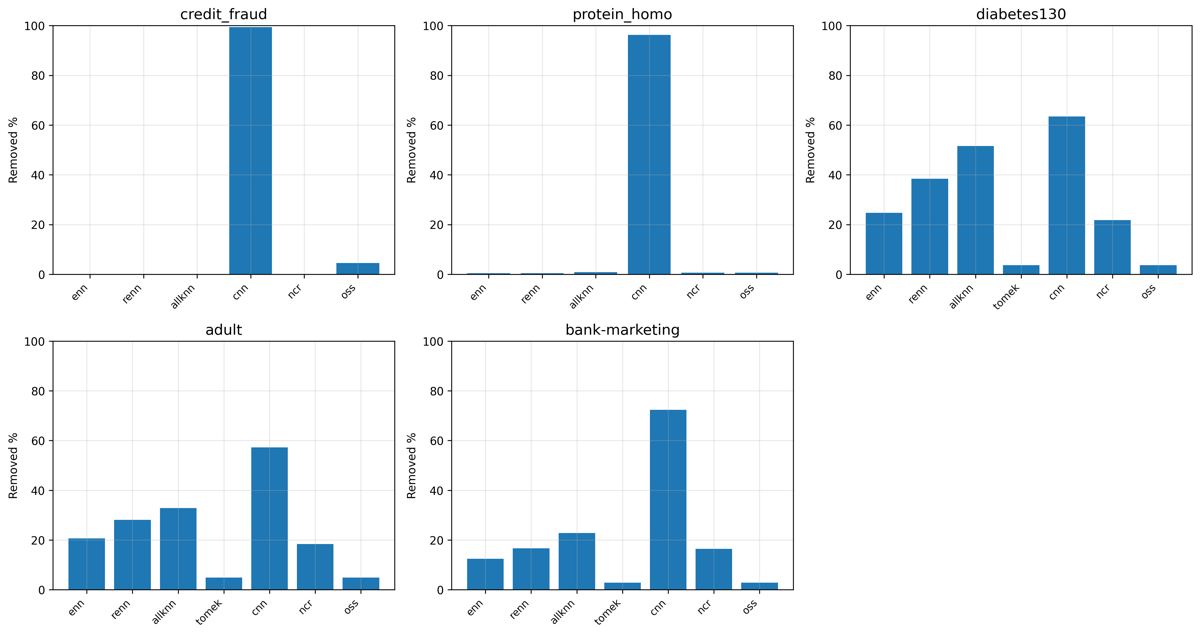
Several cleaning methods removed only a tiny fraction of the data. In general, the more the classes overlap, the more observations these methods remove.
The following figure shows the balanced accuracy of the models trained on the original data (blue) and after each cleaning method (green), together with the threshold that maximized it.
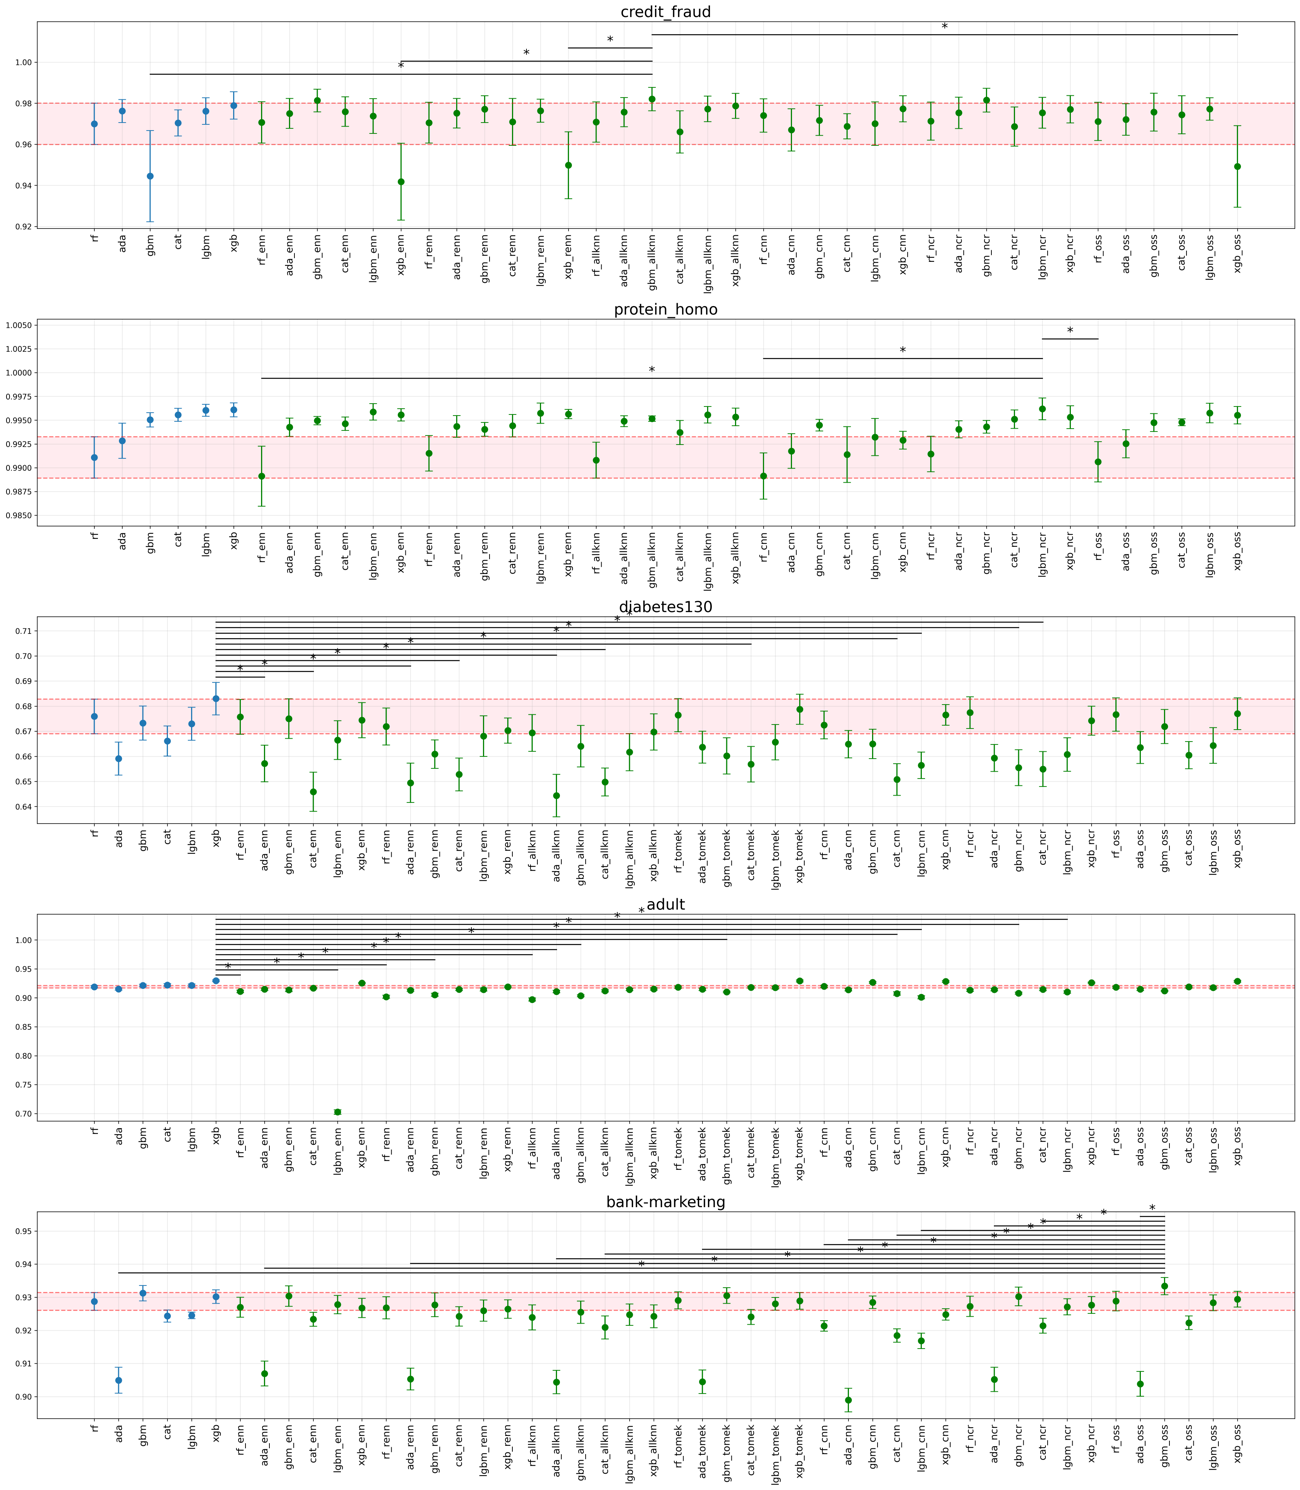
None of the cleaning methods consistently improved the performance of the models across datasets. In a few datasets, a particular combination of model and cleaning method produced a small gain, but another model trained on the original data matched or exceeded it.
In some cases, cleaning reduced performance substantially, like ENN with LightGBM on the adult dataset, or several cleaning methods with XGBoost on the credit fraud dataset. The results were consistent across the remaining 32 datasets.
Undersampling in Bagging and Boosting
What about ensembles that undersample the data while building each tree, like EasyEnsemble, RUSBoost and balanced random forests? If undersampling does not improve the performance of a model, adding it to the bagging or boosting procedure does not improve it either.
In my experiments, these resampling ensembles never consistently beat random forests or gradient boosting machines trained on the original data, and they returned poorly calibrated probabilities. I discuss these results in more detail in Should You Use Imbalanced-Learn in 2026?.
In chapter 5 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I review the original studies behind each undersampling method, the modern studies with strong classifiers, and the full results of these experiments.
So, Does Undersampling Work?
No. Undersampling does not improve the performance of modern classifiers. At best, it shifts the decision boundary so that we get good values of threshold dependent metrics at the default threshold of 0.5, and we can obtain the same result by training on the original data and lowering the threshold.
Theory backs this up: Elkan (2001) showed that changing the proportion of negative examples in the training set is equivalent to changing the decision threshold of the classifier. Resampling and threshold tuning are two routes to the same decisions.
When to Use Undersampling
The only compelling reason to undersample is computational. If your dataset is so big that training becomes prohibitively slow, random undersampling of the majority class can be a shortcut to reduce training time.
Keep in mind that cleaning methods based on KNN are slow and don’t scale, so they won’t help you there. Also, an undersampled model returns inflated probabilities, so you’ll need to recalibrate it if you need accurate probabilities.
What to Do Instead of Undersampling
The modern approach to imbalanced data goes as follows:
- Use strong classifiers, like xgboost, lightGBM or catboost.
- Train them on the original data, without resampling.
- Evaluate performance by combining a threshold independent metric, like the ROC-AUC or the PR-AUC, with a threshold dependent metric, like precision or recall.
- Tune the classification threshold to make the decisions your application needs.
I walk you through this approach in my guide to machine learning with imbalanced data.
What About Cost-Sensitive Learning?
Cost-sensitive learning with class weights set from the class imbalance does not improve model performance either. Class weights, undersampling and threshold tuning are equivalent: all three shift the decision threshold.
Having said this, if for some reason you need to make decisions at the default threshold of 0.5, class weights are a better option than undersampling. They produce the same shift in the decision boundary without discarding data.
Even better, if you know the real costs of each type of error for your business, for example, how much a missed fraudulent transaction costs compared to a false alarm, then cost-sensitive learning is the way to go.
In chapter 4 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions, I discuss everything you need to know about cost-sensitive learning for imbalanced data, from the cost matrix and the optimal threshold to class weights and instance-dependent costs.
Undersampling in Python with Imblearn
All the undersampling methods discussed in this article are available in the open-source Python library imbalanced-learn, which we import as imblearn. Each undersampler follows the scikit-learn API, and removes observations from the data with the fit_resample method.
Why I Still Show You the Undersampling Code
You will still come across undersampling in plenty of legacy code, older tutorials and Kaggle notebooks. And imblearn is a handy tool if you want to run your own experiments, and confirm that undersampling does not improve the performance of your models.
So, in the rest of this article, I’ll show you how each undersampling technique works in Python. Treat these demos as a reference to understand and maintain existing code, or to run your own comparisons, rather than as a recommendation to undersample your data.
If you do need to undersample, chapter 5 of my book Imbalanced Data: Myths, Mistakes and Modern Solutions shows you how to set up an undersampling pipeline correctly, and how to undersample once and reuse the data to tune and compare several models, which saves a lot of time with slow cleaning methods.
Creating an Imbalanced Dataset
To compare the undersampling techniques, we’ll create a toy imbalanced dataset with 2 features and some overlap between the classes. Let’s import the libraries and create the data:
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns
from sklearn.datasets import make_classification

X, y = make_classification(
    n_samples=1000,
    n_features=2,
    n_informative=2,
    n_redundant=0,
    n_clusters_per_class=1,
    weights=[0.9],
    class_sep=0.8,
    random_state=3,
)

X = pd.DataFrame(X, columns=["varA", "varB"])
y = pd.Series(y, name="class")

y.value_counts()
The dataset has 898 observations in the majority class and 102 in the minority class:
class
0    898
1    102
Name: count, dtype: int64
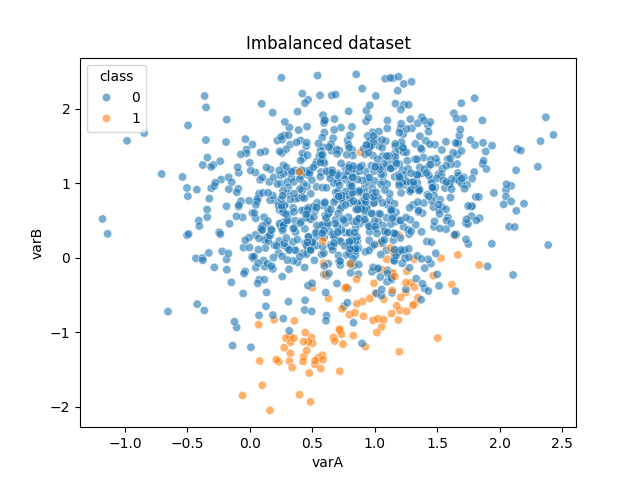
Let’s make a scatter plot to visualize the class distribution:
sns.scatterplot(data=X, x="varA", y="varB", hue=y, alpha=0.6)
plt.title("Imbalanced dataset")
plt.show()
In the following image, the blue dots are the majority class and the orange dots the minority class. Note how the classes overlap at the decision boundary:
To compare the data before and after undersampling, we’ll use the following helper function, which plots the original and the undersampled dataset side by side:
def plot_before_after(X_res, y_res, title):
    fig, axes = plt.subplots(1, 2, figsize=(12, 5), sharex=True, sharey=True)
    sns.scatterplot(data=X, x="varA", y="varB", hue=y, alpha=0.6, ax=axes[0])
    axes[0].set_title("Original dataset")
    sns.scatterplot(data=X_res, x="varA", y="varB", hue=y_res, alpha=0.6, ax=axes[1])
    axes[1].set_title(title)
    plt.tight_layout()
    plt.show()
Random Undersampling
Random undersampling removes examples from the majority class at random, until the desired balance ratio is reached. It is the simplest undersampling technique, and the one that scales best to big datasets.
Its main drawback is that it discards observations without considering how informative they are. Let’s apply random undersampling with imblearn’s RandomUnderSampler:
from imblearn.under_sampling import RandomUnderSampler

rus = RandomUnderSampler(sampling_strategy="auto", random_state=0)
X_res, y_res = rus.fit_resample(X, y)

y_res.value_counts()
With sampling_strategy="auto", the undersampler removes majority class examples until both classes have the same size:
class
0    102
1    102
Name: count, dtype: int64
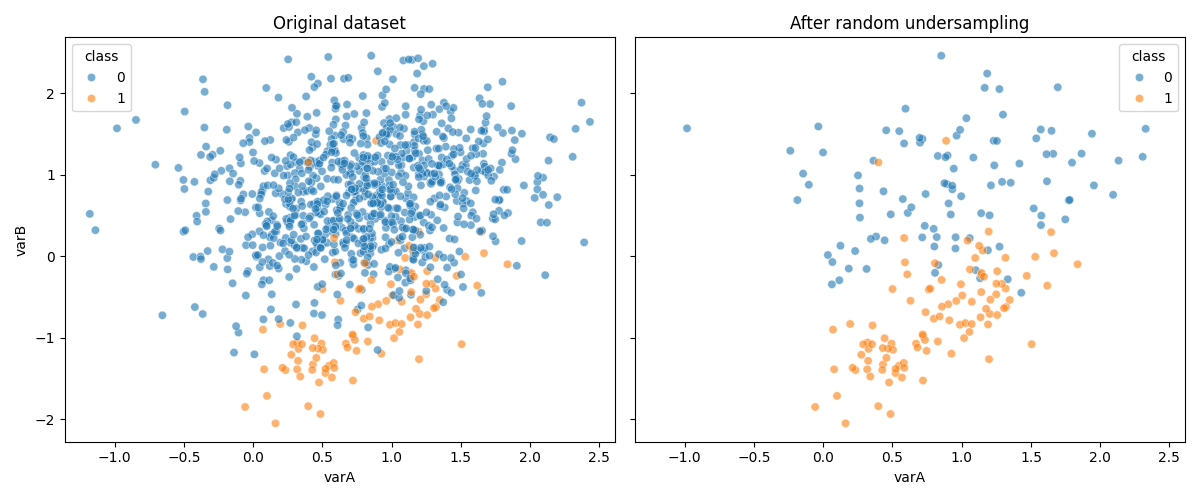
Let’s plot the data before and after random undersampling:
plot_before_after(X_res, y_res, "After random undersampling")
In the following image, we see that the majority class was thinned out uniformly across the feature space:
Changing the Sampling Strategy
We can also undersample to a different ratio, by passing a float to sampling_strategy. The float is the desired ratio of minority to majority class examples after resampling:
rus = RandomUnderSampler(sampling_strategy=0.5, random_state=0)
X_res, y_res = rus.fit_resample(X, y)

y_res.value_counts()
Now, the majority class has twice as many examples as the minority class:
class
0    204
1    102
Name: count, dtype: int64
Random undersampling does not need imblearn. You can achieve the same with pandas, for example, by sampling the rows of the majority class with DataFrame.sample().
Methods That Select Examples to Keep
NearMiss Undersampling
NearMiss, or near miss undersampling, is a family of methods that select the majority class examples to keep, based on their distance to the minority class. There are three versions of NearMiss:
- NearMiss-1 keeps the majority class examples with the smallest average distance to their k closest minority class examples.
- NearMiss-2 keeps the majority class examples with the smallest average distance to their k furthest minority class examples.
- NearMiss-3 first keeps, for each minority class example, its closest majority class neighbors, and then, among those, keeps the examples with the largest average distance to their k nearest minority class neighbors.
Let’s apply NearMiss-1 with imblearn. We select the version with the version parameter, and the number of neighbors with n_neighbors:
from imblearn.under_sampling import NearMiss

nm = NearMiss(version=1, n_neighbors=3)
X_res, y_res = nm.fit_resample(X, y)

y_res.value_counts()
NearMiss is a fixed undersampling method, so it returns a balanced dataset:
class
0    102
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After NearMiss-1")
In the following image, we see that NearMiss-1 kept only the majority class examples that sit closest to the minority class:
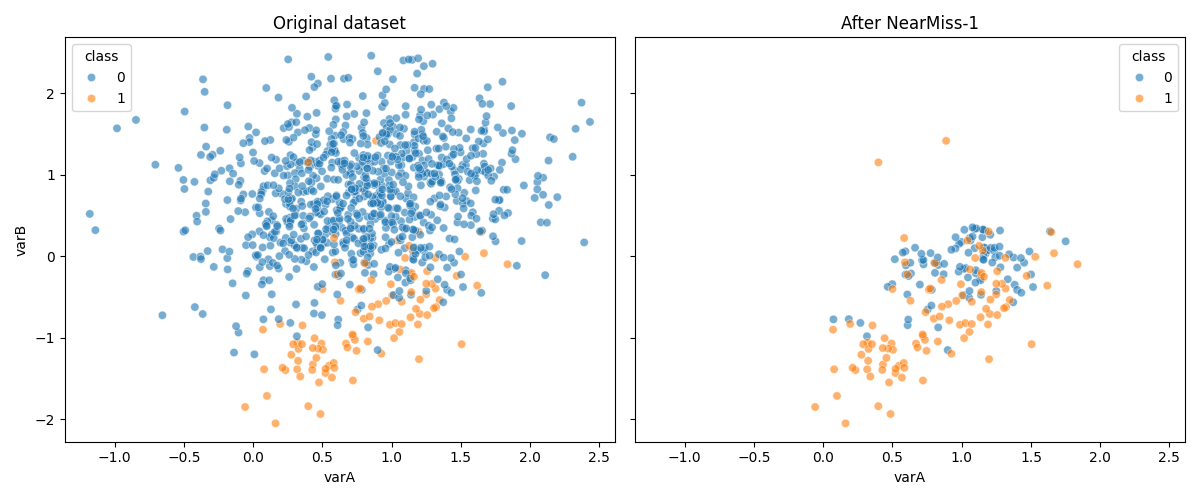
The resulting training set no longer resembles the original data distribution. The majority class examples far from the boundary, which are easy to classify, are gone, and a model trained on this data will flag many of them as the minority class. We’ll see the consequences of this in the experiment at the end of the article.
Condensed Nearest Neighbors (CNN)
Condensed nearest neighbors looks for the smallest subset of the data that a 1-nearest neighbor classifier can use to label every observation correctly. It starts with all minority class examples and one random majority class example, and then works through the remaining majority class examples one at a time.
Whenever the current classifier misclassifies an example, CNN adds it to the subset of examples to keep. The examples that are easy to classify are considered redundant and discarded, so CNN tends to keep the examples near the decision boundary.
Let’s apply condensed nearest neighbors with imblearn:
from imblearn.under_sampling import CondensedNearestNeighbour

cnn = CondensedNearestNeighbour(n_neighbors=1, random_state=0)
X_res, y_res = cnn.fit_resample(X, y)

y_res.value_counts()
CNN removed so many examples that the majority class became smaller than the minority class:
class
1    102
0     89
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After condensed nearest neighbors")
In the following image, we see that CNN kept mostly the majority class examples close to, or within, the minority class region:
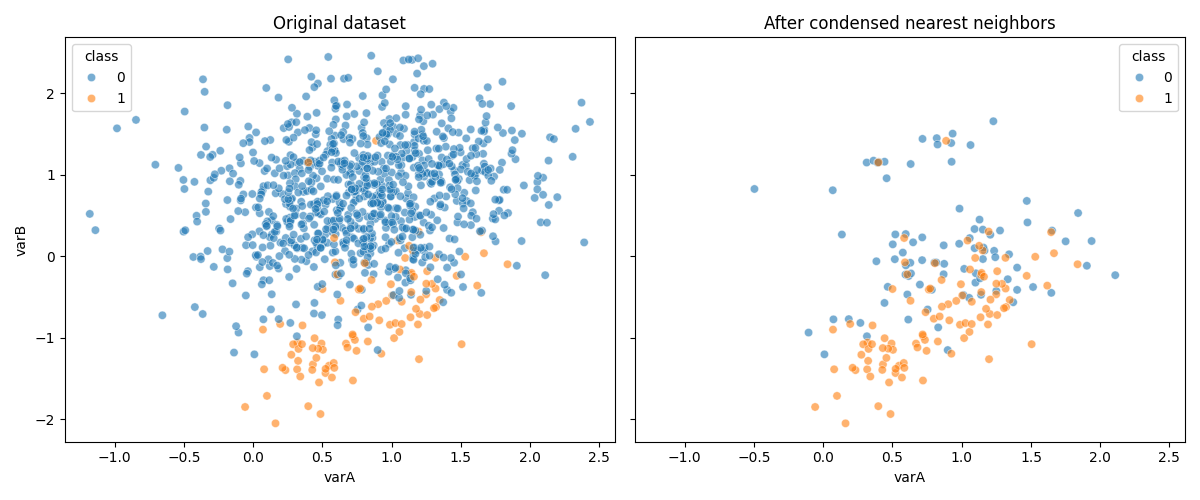
CNN is also slow, because it refits the KNN classifier every time it adds an example to the subset.
Methods That Select Examples to Delete
Tomek Links
A Tomek link is a pair of observations from different classes that are each other’s nearest neighbors. When two observations of different classes sit this close, they are borderline examples on the decision boundary, and the method treats the overlap as noise.
Tomek links undersampling removes the majority class example of each Tomek link. In its more aggressive variant, it removes both examples of the pair.
Let’s apply Tomek links with imblearn. With sampling_strategy="auto", we remove only the majority class examples:
from imblearn.under_sampling import TomekLinks

tl = TomekLinks(sampling_strategy="auto")
X_res, y_res = tl.fit_resample(X, y)

y_res.value_counts()
Tomek links removed 22 examples from the majority class:
class
0    876
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After Tomek links")
In the following image, the changes are subtle. Only a few majority class examples sitting right next to minority class examples were removed:
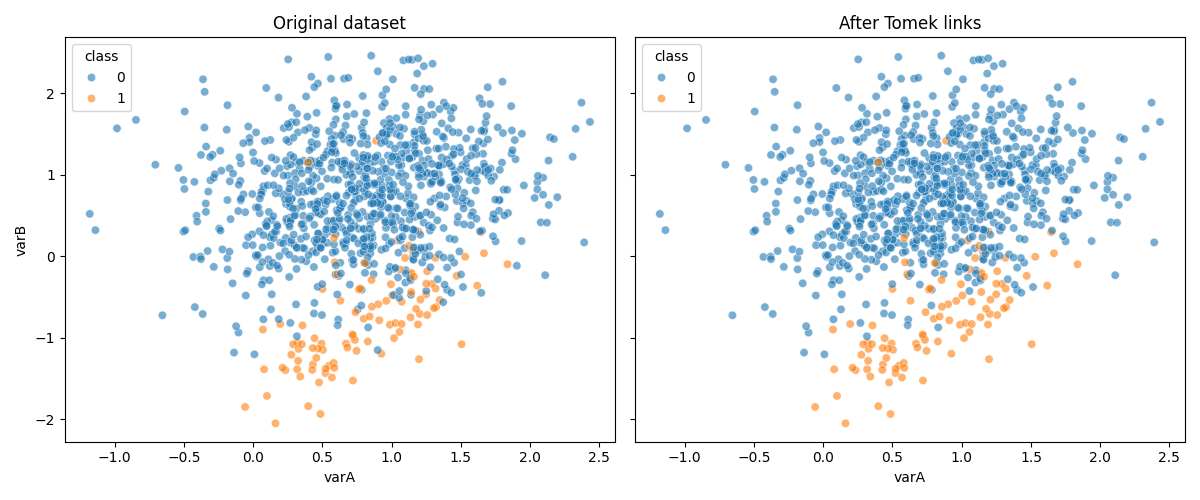
Tomek links is a cleaning method, so it does not return a balanced dataset. The more the classes overlap at the boundary, the more examples it removes.
Edited Nearest Neighbors (ENN)
Edited nearest neighbors removes majority class examples whose neighbors belong to a different class. It trains a KNN classifier, typically with 3 neighbors, and looks at the closest neighbors of each majority class example.
If the neighbors disagree with the example’s class, the example is likely noise or an outlier sitting inside minority class territory, so ENN removes it. We can require all neighbors to agree with the example’s class to keep it, or just the majority of them.
Let’s apply ENN with imblearn. With kind_sel="all", an example is kept only if all its neighbors belong to its class:
from imblearn.under_sampling import EditedNearestNeighbours

enn = EditedNearestNeighbours(sampling_strategy="auto", n_neighbors=3, kind_sel="all")
X_res, y_res = enn.fit_resample(X, y)

y_res.value_counts()
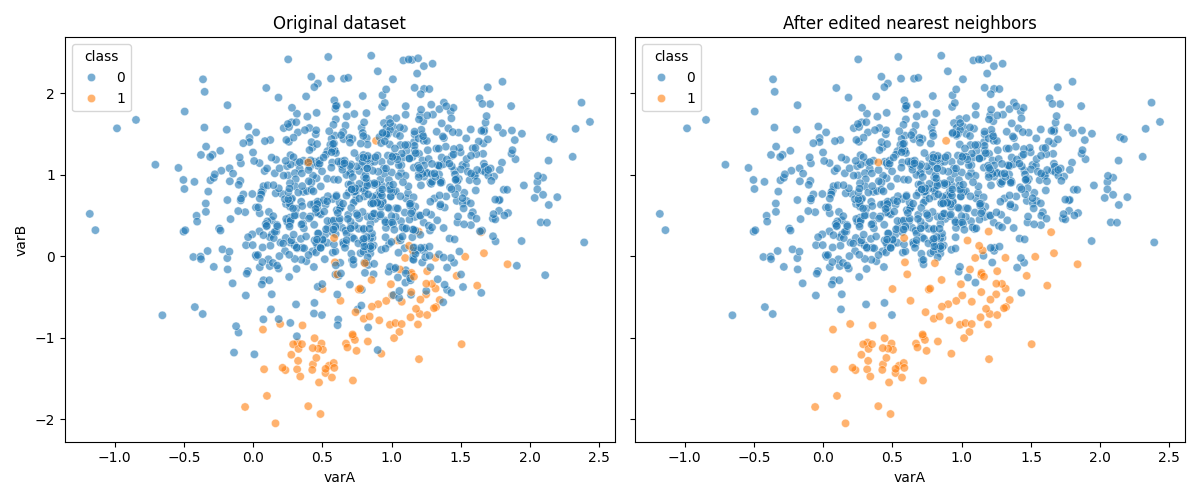
ENN removed 92 examples from the majority class, many more than Tomek links:
class
0    806
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After edited nearest neighbors")
In the following image, we see that ENN removed the majority class examples that were mixed with the minority class, so the minority class region now looks “cleaner”:
Repeated ENN and AllKNN
ENN has two variants that apply it several times. Repeated ENN (RENN) runs ENN repeatedly, until no more examples are removed or it reaches a maximum number of iterations.
AllKNN also repeats ENN, but increases the number of neighbors by one at each round, starting with one neighbor. It stops when it reaches the number of neighbors set by the user, or when the majority class would become smaller than the minority class.
Let’s apply both with imblearn:
from imblearn.under_sampling import AllKNN, RepeatedEditedNearestNeighbours

renn = RepeatedEditedNearestNeighbours(n_neighbors=3, max_iter=100)
allknn = AllKNN(n_neighbors=3)

for undersampler in [renn, allknn]:
    X_res, y_res = undersampler.fit_resample(X, y)
    print(type(undersampler).__name__, y_res.value_counts().to_dict())
Both remove more examples than a single round of ENN:
RepeatedEditedNearestNeighbours {0: 783, 1: 102}
AllKNN {0: 790, 1: 102}
Instance Hardness Threshold
The instance hardness threshold removes majority class examples that are hard to classify. It trains a classifier with cross-validation, and obtains the probability that each example belongs to its true class.
The instance hardness is one minus that probability. Examples with high hardness tend to lie where the classes overlap, and the method removes the hardest majority class examples, aiming for a balanced dataset.
In practice, many examples share the same probability, so the method often removes fewer examples than needed to balance the classes.
Let’s apply the instance hardness threshold with imblearn, using a random forest to estimate the hardness:
from imblearn.under_sampling import InstanceHardnessThreshold
from sklearn.ensemble import RandomForestClassifier

iht = InstanceHardnessThreshold(
    estimator=RandomForestClassifier(random_state=0),
    cv=5,
    random_state=0,
)
X_res, y_res = iht.fit_resample(X, y)

y_res.value_counts()
The instance hardness threshold removed 274 examples from the majority class:
class
0    624
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After instance hardness threshold")
In the following image, we see a clear gap between the classes. The method removed every majority class example in the region where the classes overlap:
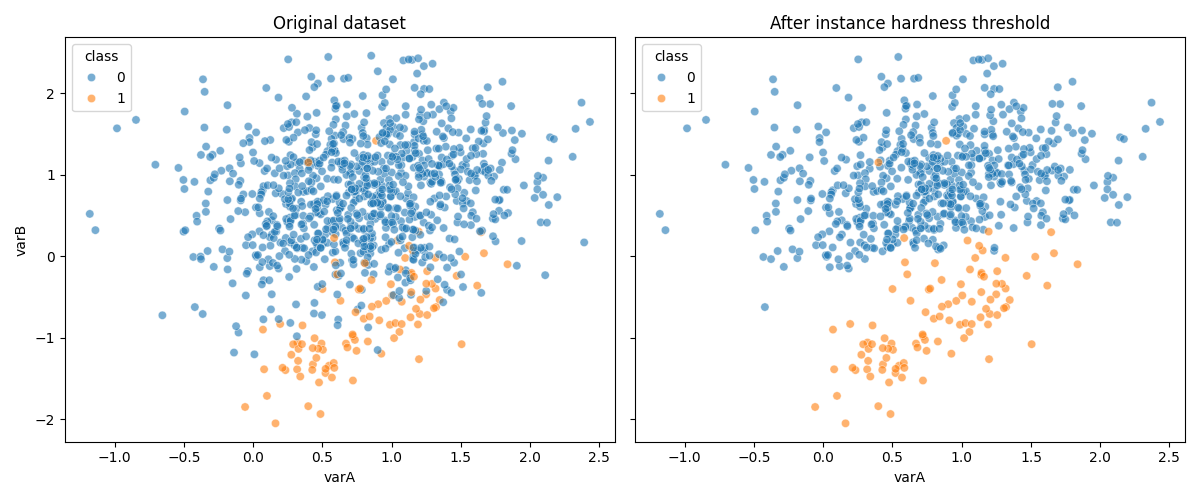
Note that the hardness depends on the classifier used to estimate it, so different classifiers will remove different examples.
Methods That Combine Keep and Delete
One-Sided Selection (OSS)
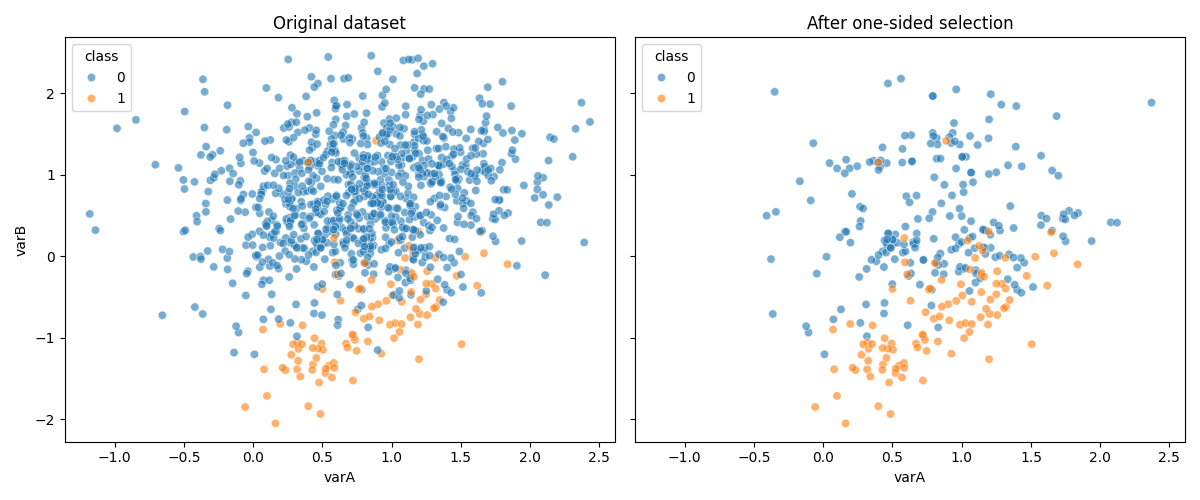
One-sided selection combines a single pass of condensed nearest neighbors with Tomek links. It starts with all minority class examples plus a few random majority class examples, the seeds, and trains a 1-nearest neighbor classifier on them.
The classifier then predicts the rest of the majority class. The examples it classifies correctly are considered redundant and discarded, while the misclassified ones are kept.
Finally, it removes Tomek links, to delete the noisy majority class examples that sit right on the boundary. One-sided selection therefore removes both redundant and noisy examples.
The n_seeds_S parameter sets the number of seeds. With the default value of 1, the classifier misclassifies almost every majority class example, so OSS behaves much like Tomek links.
Let’s apply one-sided selection with imblearn, using 100 seeds:
from imblearn.under_sampling import OneSidedSelection

oss = OneSidedSelection(n_neighbors=1, n_seeds_S=100, random_state=0)
X_res, y_res = oss.fit_resample(X, y)

y_res.value_counts()
One-sided selection removed 681 examples from the majority class:
class
0    217
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After one-sided selection")
In the following image, we see that one-sided selection discarded most of the majority class examples far from the minority class, and kept those closer to the decision boundary:
Neighborhood Cleaning Rule (NCR)
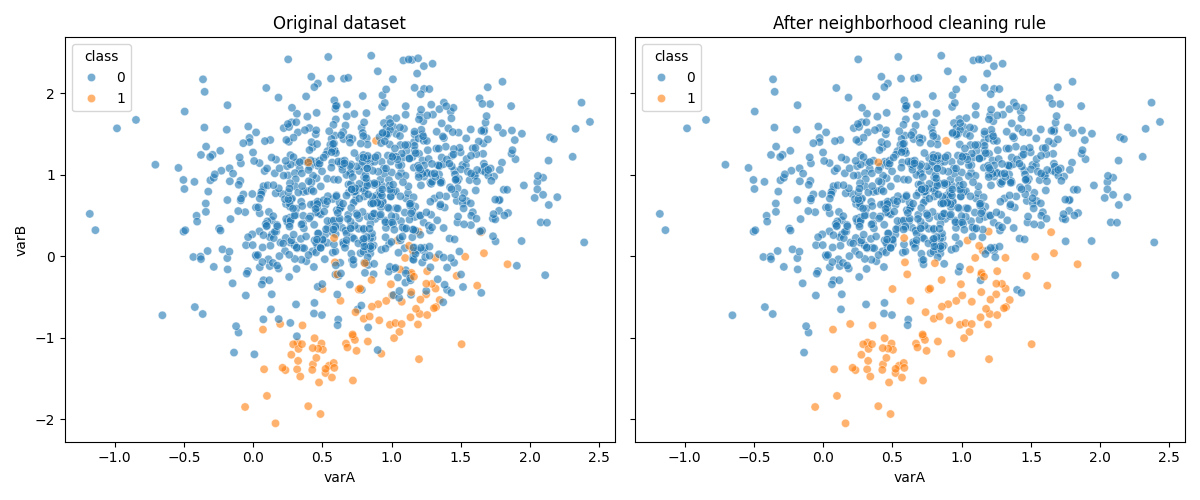
The neighborhood cleaning rule extends ENN with a second cleaning step. It first runs ENN to remove the majority class examples whose neighbors disagree with them.
Then, it looks at the 3 nearest neighbors of each minority class example, and removes the majority class neighbors that would misclassify it. In this way, it cleans the decision boundary from both sides.
Let’s apply the neighborhood cleaning rule with imblearn:
from imblearn.under_sampling import NeighbourhoodCleaningRule

ncr = NeighbourhoodCleaningRule(n_neighbors=3, threshold_cleaning=0.5)
X_res, y_res = ncr.fit_resample(X, y)

y_res.value_counts()
The neighborhood cleaning rule removed 79 examples from the majority class:
class
0    819
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After neighborhood cleaning rule")
In the following image, we see that, like ENN, the neighborhood cleaning rule removed the majority class examples that were mixed with the minority class:
Cluster Centroids Undersampling
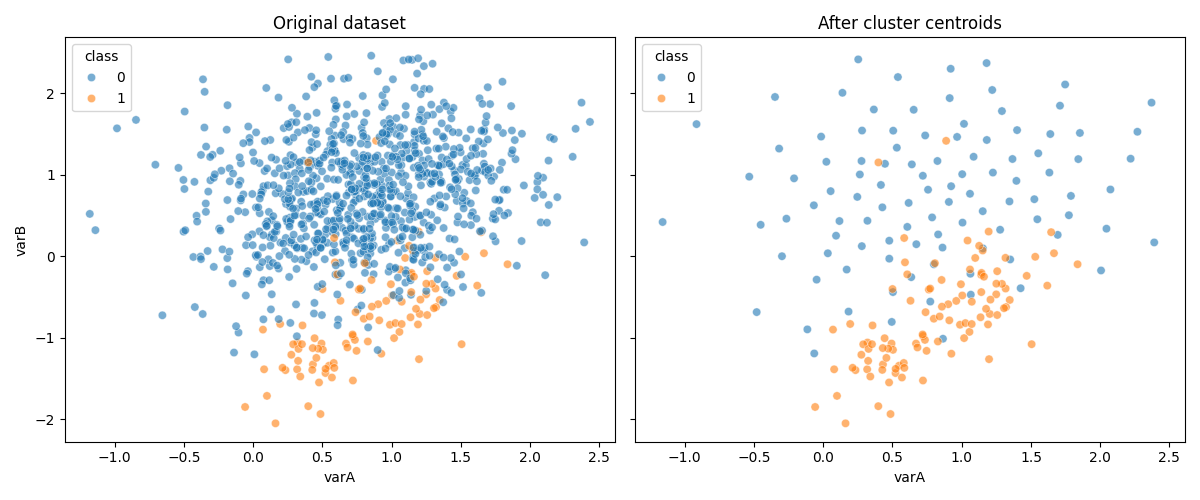
Cluster centroids takes a different approach. Instead of selecting examples from the majority class, it groups the majority class into clusters with k-means, and replaces the original examples with the cluster centroids.
By default, it creates as many clusters as there are minority class examples, so it returns a balanced dataset made of synthetic majority class examples. Let’s apply it with imblearn:
from imblearn.under_sampling import ClusterCentroids

cc = ClusterCentroids(random_state=0)
X_res, y_res = cc.fit_resample(X, y)

y_res.value_counts()
The majority class now has 102 examples, one per cluster:
class
0    102
1    102
Name: count, dtype: int64
Let’s plot the data:
plot_before_after(X_res, y_res, "After cluster centroids")
In the following image, we see that the cluster centroids are spread across the majority class region, so they summarize the original distribution better than NearMiss or CNN:
Combining Undersampling and Oversampling
Imblearn also supports hybrid sampling methods that combine SMOTE with Tomek links or ENN:
from imblearn.combine import SMOTEENN, SMOTETomek

for resampler in [SMOTETomek(random_state=0), SMOTEENN(random_state=0)]:
    X_res, y_res = resampler.fit_resample(X, y)
    print(type(resampler).__name__, y_res.value_counts().to_dict())
SMOTETomek returns a balanced dataset, while SMOTEENN removes examples from both classes after oversampling:
SMOTETomek {0: 865, 1: 865}
SMOTEENN {1: 796, 0: 744}
Does Undersampling Improve Performance? A Python Experiment
Now, let’s use imblearn to check whether undersampling improves the performance of a strong classifier. We’ll create a harder dataset with 10 features and 5% of observations in the minority class, and compare a gradient boosting model trained on the original data with the same model trained after various undersampling methods.
We’ll evaluate each model with repeated cross-validation, and report the mean and standard deviation of the ROC-AUC, PR-AUC, Brier score and balanced accuracy. We’ll also add a model trained on the original data whose threshold is tuned to maximize the balanced accuracy, using scikit-learn’s TunedThresholdClassifierCV.
import pandas as pd
from sklearn.datasets import make_classification
from sklearn.ensemble import HistGradientBoostingClassifier
from sklearn.model_selection import (
    RepeatedStratifiedKFold,
    TunedThresholdClassifierCV,
    cross_validate,
)

from imblearn.pipeline import Pipeline
from imblearn.under_sampling import (
    EditedNearestNeighbours,
    NearMiss,
    NeighbourhoodCleaningRule,
    RandomUnderSampler,
    TomekLinks,
)

X, y = make_classification(
    n_samples=10000,
    n_features=10,
    n_informative=5,
    weights=[0.95, 0.05],
    flip_y=0.01,
    class_sep=0.8,
    random_state=0,
)

undersamplers = {
    "random undersampling": RandomUnderSampler(random_state=0),
    "tomek links": TomekLinks(),
    "enn": EditedNearestNeighbours(),
    "ncr": NeighbourhoodCleaningRule(),
    "nearmiss-1": NearMiss(version=1),
}

models = {"original": HistGradientBoostingClassifier(random_state=0)}

for name, undersampler in undersamplers.items():
    models[name] = Pipeline([
        ("undersampler", undersampler),
        ("model", HistGradientBoostingClassifier(random_state=0)),
    ])

models["original + tuned threshold"] = TunedThresholdClassifierCV(
    HistGradientBoostingClassifier(random_state=0),
    scoring="balanced_accuracy",
)

cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=0)

scoring = {
    "roc_auc": "roc_auc",
    "pr_auc": "average_precision",
    "brier": "neg_brier_score",
    "bal_acc": "balanced_accuracy",
}

results = {}
for name, model in models.items():
    scores = cross_validate(model, X, y, cv=cv, scoring=scoring, n_jobs=-1)
    results[name] = {
        metric: f"{abs(scores[f'test_{metric}'].mean()):.3f} ± {scores[f'test_{metric}'].std():.3f}"
        for metric in scoring
    }

print(pd.DataFrame(results).T.to_string())
The code returns the following results:
                                  roc_auc         pr_auc          brier        bal_acc
original                    0.904 ± 0.019  0.608 ± 0.044  0.032 ± 0.002  0.676 ± 0.023
random undersampling        0.883 ± 0.018  0.414 ± 0.043  0.139 ± 0.007  0.826 ± 0.018
tomek links                 0.902 ± 0.019  0.611 ± 0.046  0.032 ± 0.002  0.685 ± 0.025
enn                         0.901 ± 0.019  0.583 ± 0.039  0.033 ± 0.003  0.737 ± 0.025
ncr                         0.903 ± 0.021  0.589 ± 0.044  0.033 ± 0.002  0.722 ± 0.018
nearmiss-1                  0.578 ± 0.035  0.092 ± 0.029  0.578 ± 0.023  0.545 ± 0.017
original + tuned threshold  0.904 ± 0.019  0.608 ± 0.044  0.032 ± 0.002  0.840 ± 0.020
Interpreting the Results
None of the undersampling methods improved the ROC-AUC or the PR-AUC. Tomek links, ENN and NCR performed similarly to the original model, random undersampling reduced the PR-AUC, and NearMiss-1 destroyed the performance of the model, because it trained on a distorted version of the majority class.
Random undersampling also quadrupled the Brier score, which means that the predicted probabilities became much less accurate. This is the miscalibration we saw in my experiments across 37 datasets.
Now look at the balanced accuracy. At the default threshold of 0.5, random undersampling seems to improve it from 0.676 to 0.826.
But the original model with a tuned threshold reaches 0.840, without discarding any data. Undersampling only shifted the threshold.
Undersampling Mistakes to Avoid
Undersampling the Test Set
Undersample only the training data, and never the test set or the validation folds. Otherwise, we evaluate the model on a class distribution that does not exist in reality, and the performance metrics will be misleading.
Undersampling Before Cross-Validation
Undersampling the whole dataset before cross-validation causes data leakage, because the validation folds no longer reflect the original class distribution, and cleaning methods use information from the validation examples to decide what to remove. Instead, add the undersampler to imblearn’s Pipeline, as we did in the experiment, so that it is applied only to the training folds.
Evaluating at the Default Threshold
Comparing threshold dependent metrics like recall, F1-score or balanced accuracy at the default threshold of 0.5 will make undersampling look better than it is. Compare models with threshold independent metrics, and tune the threshold before computing the threshold dependent ones.
Ignoring the Scale and Type of the Features
Most undersampling methods use KNN, which relies on distances. Scale the features before undersampling, and keep in mind that distances like the Euclidean distance are not suitable for categorical variables.
Conclusion
Undersampling reduces the number of observations in the majority class to balance an imbalanced dataset. There are many undersampling techniques, from random undersampling to NearMiss, condensed nearest neighbors, Tomek links, edited nearest neighbors, the instance hardness threshold, one-sided selection, the neighborhood cleaning rule and cluster centroids.
The evidence from the literature, and from my own experiments across 37 datasets, shows that undersampling does not improve the performance of modern classifiers. It shifts the decision threshold and distorts the predicted probabilities, and we can get the same decisions by training on the original data and tuning the threshold.
So, does undersampling help with imbalanced data? Rarely. Use it as a shortcut to reduce training time on huge datasets, use imblearn to maintain legacy code or run your own experiments, and otherwise, train strong classifiers on the original data.
If you want to learn more about working with imbalanced datasets, check out my book Imbalanced Data: Myths, Mistakes and Modern Solutions.
References
- Elkan, C. 2001. The Foundations of Cost-Sensitive Learning. IJCAI.
- Galli, S. 2026. Resampling experiments code repository.
- Galli, S. 2026. Imbalanced Data: Myths, Mistakes and Modern Solutions.
- Hasanin, T. et al. 2019. Severely imbalanced Big Data challenges: investigating data sampling approaches. Journal of Big Data.
- Kim, M. et al. 2022. An empirical evaluation of sampling methods for the classification of imbalanced data. PLOS ONE.
- Wainer, J. 2023. An empirical evaluation of imbalanced data strategies from a practitioner’s point of view. arXiv.
- Imbalanced-learn documentation: Under-sampling.
